From Java Backend to AI Agents: A Complete Path to Production Delivery
A backend developer recently asked me a familiar question during a livestream: their company had started adopting AI platforms, and they could already assemble workflows and call model APIs, yet it still felt like they were only touching the shell. What was missing before they could apply for an Agent role? Did interviews still test computer-science fundamentals? Should they choose a large company or an AI startup?
To protect the caller, this article removes their age, city, employer, specific business and personal tooling. What remains is the part many experienced developers have in common.
Here is the short answer:
A Java developer does not need to erase their past to move into AI. The practical path is to become an LLM application engineer with strong business and backend skills, not to compete from day one with researchers training foundation models.
The missing layer is not another programming-language syllabus. It is model behavior, RAG, tool use, evaluation and production AI engineering. The goal is not merely to operate a platform. It is to understand why the system works, why it fails and how to improve it with evidence even after the platform is removed.
Define the target role first
“AI job” is not one job. Agent-related openings usually fall into at least four groups:
| Direction | Main responsibility | Transition from Java |
|---|---|---|
| LLM / Agent application engineer | RAG, tool use, workflows, evaluation, model integration | Most direct |
| AI backend engineer | Model gateways, APIs, data flows, authorization and reliability | Most direct |
| AI full-stack engineer | AI backend plus product UI and end-to-end delivery | Reasonably direct |
| Model / ML engineer | Training, fine-tuning, inference optimization, papers and GPUs | More demanding |
Titles remain inconsistent. “LLM application developer,” “AI application engineer,” “RAG engineer” and “Agent engineer” may describe the same work. Two Agent roles may also be completely different: one owns a backend platform while another runs model experiments.
Read the responsibilities, not just the title. Ask who receives the deliverable, whether the team trains models and whether the role owns a live production system.
When the job connects existing models to a real business and owns quality, cost and reliability, Java experience is an advantage. APIs, databases, caches, queues, concurrency, authorization, auditing and recovery are exactly what an Agent needs after the demo.
From platform operation to complete engineering
Low-code platforms are valuable. They make nodes, variables, branches, retrieval and tools visible, and they let a team test whether an idea deserves further investment.
They also hide complexity.
Uploading documents does not prove that you understand parsing, chunking, embeddings or retrieval. Calling an API does not handle timeouts, idempotency or authorization. Passing a preview does not provide production logs, alerts, rollback or cost control.
Use five questions to test whether you have moved beyond platform operation:
- Could I draw and implement the core flow if Dify disappeared?
- When an answer is wrong, can I separate parsing, retrieval, generation and tool failures?
- After changing a prompt, model or corpus, how do I prove that the new version is better?
- What happens when the model or an external API times out?
- How do I stop one tenant from retrieving another tenant's data?
If these are difficult, that is fine. They are your next curriculum.
The six layers a Java developer should add
1. Model application fundamentals
Learn tokens, context windows, system prompts, structured output, sampling, embeddings, function calling and the common sources of hallucination.
You do not need to derive the Transformer first. You do need to know whether a quality, latency or cost regression points to the context, the model, its parameters or the surrounding application.
2. Debug RAG as a pipeline
RAG is more than “upload documents and attach a model.” It includes parsing and cleanup, chunking strategy, overlap, metadata and authorization, vector and keyword retrieval, hybrid search, Top K, thresholds, reranking, query rewriting, citations and refusal when evidence is missing.
A user sees one wrong answer. An engineer separates two questions: did the system retrieve the correct evidence, and did the model answer faithfully after receiving it? The first is retrieval; only the second is generation.
3. Let Agents use tools safely
Tool use requires precise schemas, limited permissions and stable return structures. It also needs timeouts, bounded retries, duplicate-call protection, loop termination and human approval.
In enterprise systems, more autonomy is not automatically better. For writes, messages, submissions or other side effects, a deterministic workflow should usually enforce the boundary while the model handles only the parts that require interpretation.
4. Build an evaluation loop
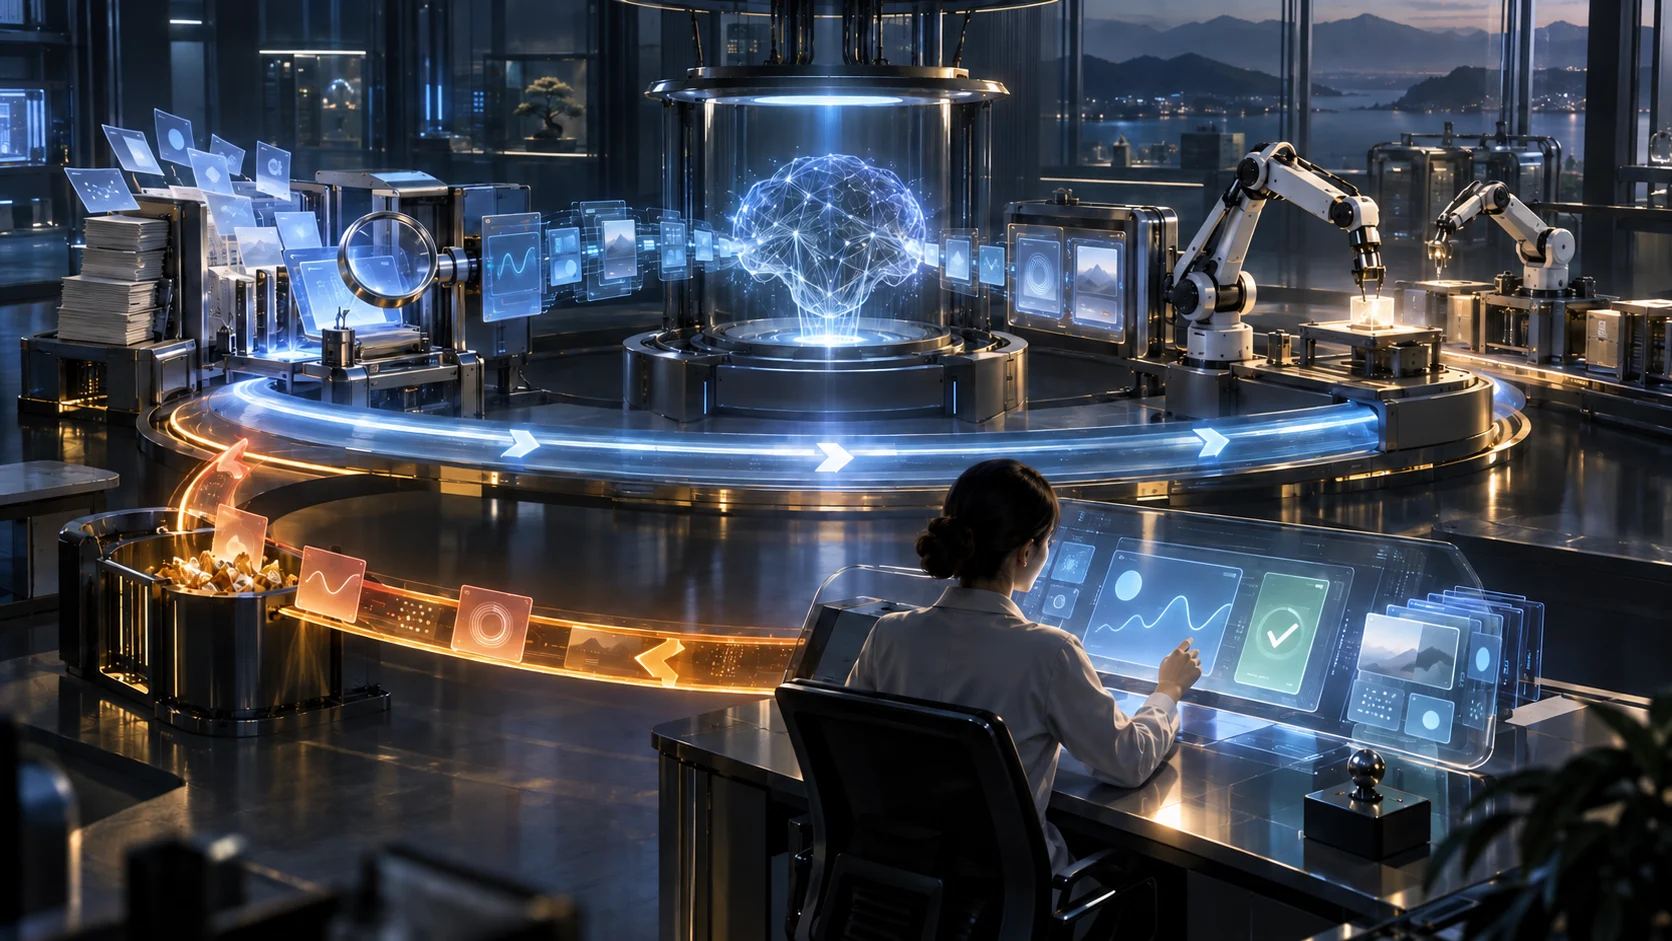
Trying ten questions and saying “it feels good” is not evaluation.
Measure at least three layers:
| Layer | Example metrics |
|---|---|
| Retrieval | Recall@K, correct-evidence hit rate and rank |
| Generation | Correctness, faithfulness, completeness, citation accuracy and refusal |
| Agent | Task completion, tool and argument accuracy, steps, latency and cost |
Create a Golden Dataset from the business domain, then combine deterministic checks, human review and LLM-as-a-Judge. Run the same regression set whenever the model, prompt, chunks or retrieval settings change.
Ragas, DeepEval and LangSmith can help, but tool names are not the point. A strong project explains where its cases came from, what counts as failure, how metrics moved and how severe errors are contained.
Some teams call the infrastructure that runs, records and compares these tests an evaluation harness. Here, “harness” is a generic test rig, not a separate technology alongside RAG or Dify.
5. Add production engineering
This is where backend experience compounds:
- streaming, asynchronous jobs and concurrency control;
- rate limits, timeouts, retries, circuit breakers and degradation;
- model routing and provider failover;
- versioning for prompts, corpora and models;
- traces, logs, tokens, P95 latency and cost per task;
- staged rollout, regression checks and rollback;
- user, tenant and knowledge-level authorization.
AI coding tools can generate unfamiliar syntax. They cannot decide transaction boundaries, data consistency or recovery policy for you. As code becomes cheaper to produce, engineering judgment becomes more valuable.
6. Treat security and compliance as features
Regulated domains must address prompt injection, sensitive data, cross-tenant retrieval, output redaction, tool allowlists, human confirmation and audit logs.
Do not ask only how often the system is correct. Ask what happens when it is wrong, whether it knows when evidence is missing, whether it can show its sources and whether it refuses appropriately.
Define launch criteria with layered metrics
A launch threshold becomes useful only when the evaluated task, sample distribution and cost of failure are explicit. “95% accuracy” could describe FAQ answers, retrieval recall, field extraction or successful tool calls; those measurements are not interchangeable.
A low-risk internal search tool may launch gradually below 95% with citations, limited scope and human fallback. A high-risk recommendation affecting underwriting, claims or health may remain unacceptable even at 99% if the remaining failures are severe.
Split the scenario by risk and set separate gates for evidence retrieval, faithfulness, severe-error rate, refusal, human approval, latency, cost and dependency failure. Average accuracy is useful context; it is not an accountability model.
Design the portfolio for the target role
Portfolio projects can follow two strong paths. A multimodal story generator demonstrates scripts, images, video, TTS, ASR and orchestration. A vertical business assistant demonstrates RAG, tool use, evaluation, authorization and production engineering. Choose the path that matches the target role.
Using only public and synthetic data, build an insurance-policy assistant with a claims-document pre-check:
- Import public policies, document checklists and FAQs.
- Model product, version, region and effective date as metadata.
- Require citations in every supported answer.
- Refuse when evidence is missing or the product does not match.
- Call simulated policy, document and claim-status tools.
- Route high-risk conclusions to a human.
- Prepare 100–300 sanitized evaluation cases.
- Report retrieval, answer, refusal and tool metrics plus P95 latency and cost.
- Record at least three before-and-after iterations.
- Publish the architecture, setup, evaluation report and known limits on GitHub.
The value is not the number of frameworks. It is your ability to explain what failed in version one, how you found the cause, what changed, how the metrics moved and what remains unresolved.
Never publish customer data, internal documents, production prompts, endpoints, secrets or logs. Public material, simulated APIs and synthetic tests are enough to demonstrate the engineering.
The learning boundary across Java, Python and frontend
The answer is neither “master everything” nor “learn nothing.”
Java can remain your primary language, with Spring AI or LangChain4j supporting model and RAG applications. But many AI SDKs, evaluation tools and examples arrive in Python first, so you should at least be able to read code, modify a demo, run a notebook and diagnose dependencies.
You do not need a full React curriculum before starting, but you should be able to deliver a basic chat interface with streaming, uploads, citations and feedback. AI coding tools lower the syntax barrier; you still own correctness.
Start with the backend in Java, add enough Python for experiments, then build only the product UI you need. Do not lose months to language trivia unrelated to the target role.
The structure of an Agent interview
Yes, but the weighting has changed.
An early startup may spend most of an interview on projects and system design. Larger and mature teams may still test algorithms, Java concurrency, databases, networking and distributed systems. Backend-platform roles test more engineering; model-heavy roles expect more Python, ML and model fundamentals.
Agent interviews add questions such as:
- Why use RAG instead of fine-tuning?
- How would you diagnose “bad retrieval”?
- How do you evaluate a task with no single correct wording?
- How do you stop duplicate tool calls or infinite loops?
- How does the product degrade when a model provider times out?
- How do you prevent cross-tenant retrieval?
- How do you prove a prompt update did not break old behavior?
- How do you balance quality, P95 latency and cost?
Fundamentals did not disappear. They became the baseline, while production experience and diagnostic thinking create the separation.
How to evaluate compensation
“Agent” is not a standardized level. Job listings span ordinary application development, senior ML and architecture. City, education, experience, company stage and job type can produce very different ranges.
A practical method is to collect 30–50 current listings for your city and experience level across several keywords—LLM application, AI backend, Agent and RAG—then compare median pay, responsibilities and recurring skills. This range is more relevant to an individual candidate than any single highly paid listing.
Strong backend experience plus a verifiable Agent project may earn a premium. Merely knowing Dify does not guarantee one.
Choosing between a large company and an AI startup
The two environments offer different resources, learning density and risk. Ask:
- Is AI in production, or mainly used in demos and presales?
- Are there real users, data and a quality feedback loop?
- Does the role own core engineering or mostly on-site integration?
- Does the team have evaluation, monitoring, security and release discipline?
- Has the direct manager shipped an AI product?
- What are the compensation structure, runway, turnover and actual working rhythm?
AI tools increase coding throughput; they do not erase shifting requirements, data work, tuning, incidents or customer delivery. Workload follows management and business stage, not the words “AI Native.”
An experienced developer should not present themselves as a beginner changing careers. A stronger position is:
An experienced backend and domain engineer upgrading into production AI application delivery.
Companies need more than people who can call a model. They need engineers who can connect it to existing systems, understand business risk and own the outcome.
A 12-week path you can execute
Weeks 1–4: Call it
Learn model APIs, tokens, structured output, prompting and function calling. Use Dify to understand workflow concepts while implementing the core path with Spring AI or LangChain4j. Build enough Python literacy to modify AI examples.
Deliverable: an assistant that calls two or three simulated business tools.
Weeks 5–8: Build it
Learn parsing, chunking, embeddings, vector and keyword retrieval, reranking, citations and refusal. Build the first Golden Dataset and evaluate retrieval separately from generation.
Deliverable: a vertical knowledge assistant using public sources, with citations and an evaluation report.
Weeks 9–12: Operate it
Add tracing, logs, authorization, redaction, timeouts, retries, degradation, cost and latency monitoring. Version prompts and corpora, then rehearse a staged rollout and rollback.
Deliverable: a live demo, repository, architecture, evaluation data and honest retrospective.
The transition adds a new engineering layer
Moving from Java to Agents is not replacing .java with .py, or replacing APIs with draggable nodes.
Traditional systems are mostly deterministic. Once a model enters the path, prompts, data, model versions and user phrasing can all change the result. Engineering gains a new responsibility: define what “good” means, measure it continuously and constrain the system when it is unreliable.
The safest transition is not to chase every framework. Complete one loop:
Choose a real problem you understand, build it with public data, prove its quality with evaluation, protect it with engineering controls, and publish an honest account of failures and improvements.
At that point, you are no longer a Java developer who has merely used AI tools. You are already doing the work of an AI application engineer.
Further reading
- Ragas: systematic evaluation for RAG and LLM applications
- LangSmith Observability
- LangSmith application-specific evaluation approaches
- OWASP Top 10 for LLM Applications
- OWASP AI Testing Guide
Source and market boundary: Technical references were checked on 14 September 2026. Job titles, compensation and interview practices change quickly. This article offers a decision framework; it does not present scattered job listings as market statistics.